I am a Postdoctoral Researcher at the Stanford Institute for Human-Centered AI, and part of the Stanford HCI Group and the SHAPE Lab. I recently received my Ph.D. from the Human-Computer Interaction Institute in the School of Computer Science at Carnegie Mellon University, advised by Nik Martelaro. My research has been supported by Google, Toyota Research Institute, Adobe Research, Runway, Accenture Labs, NSF, and the Office of Naval Research.
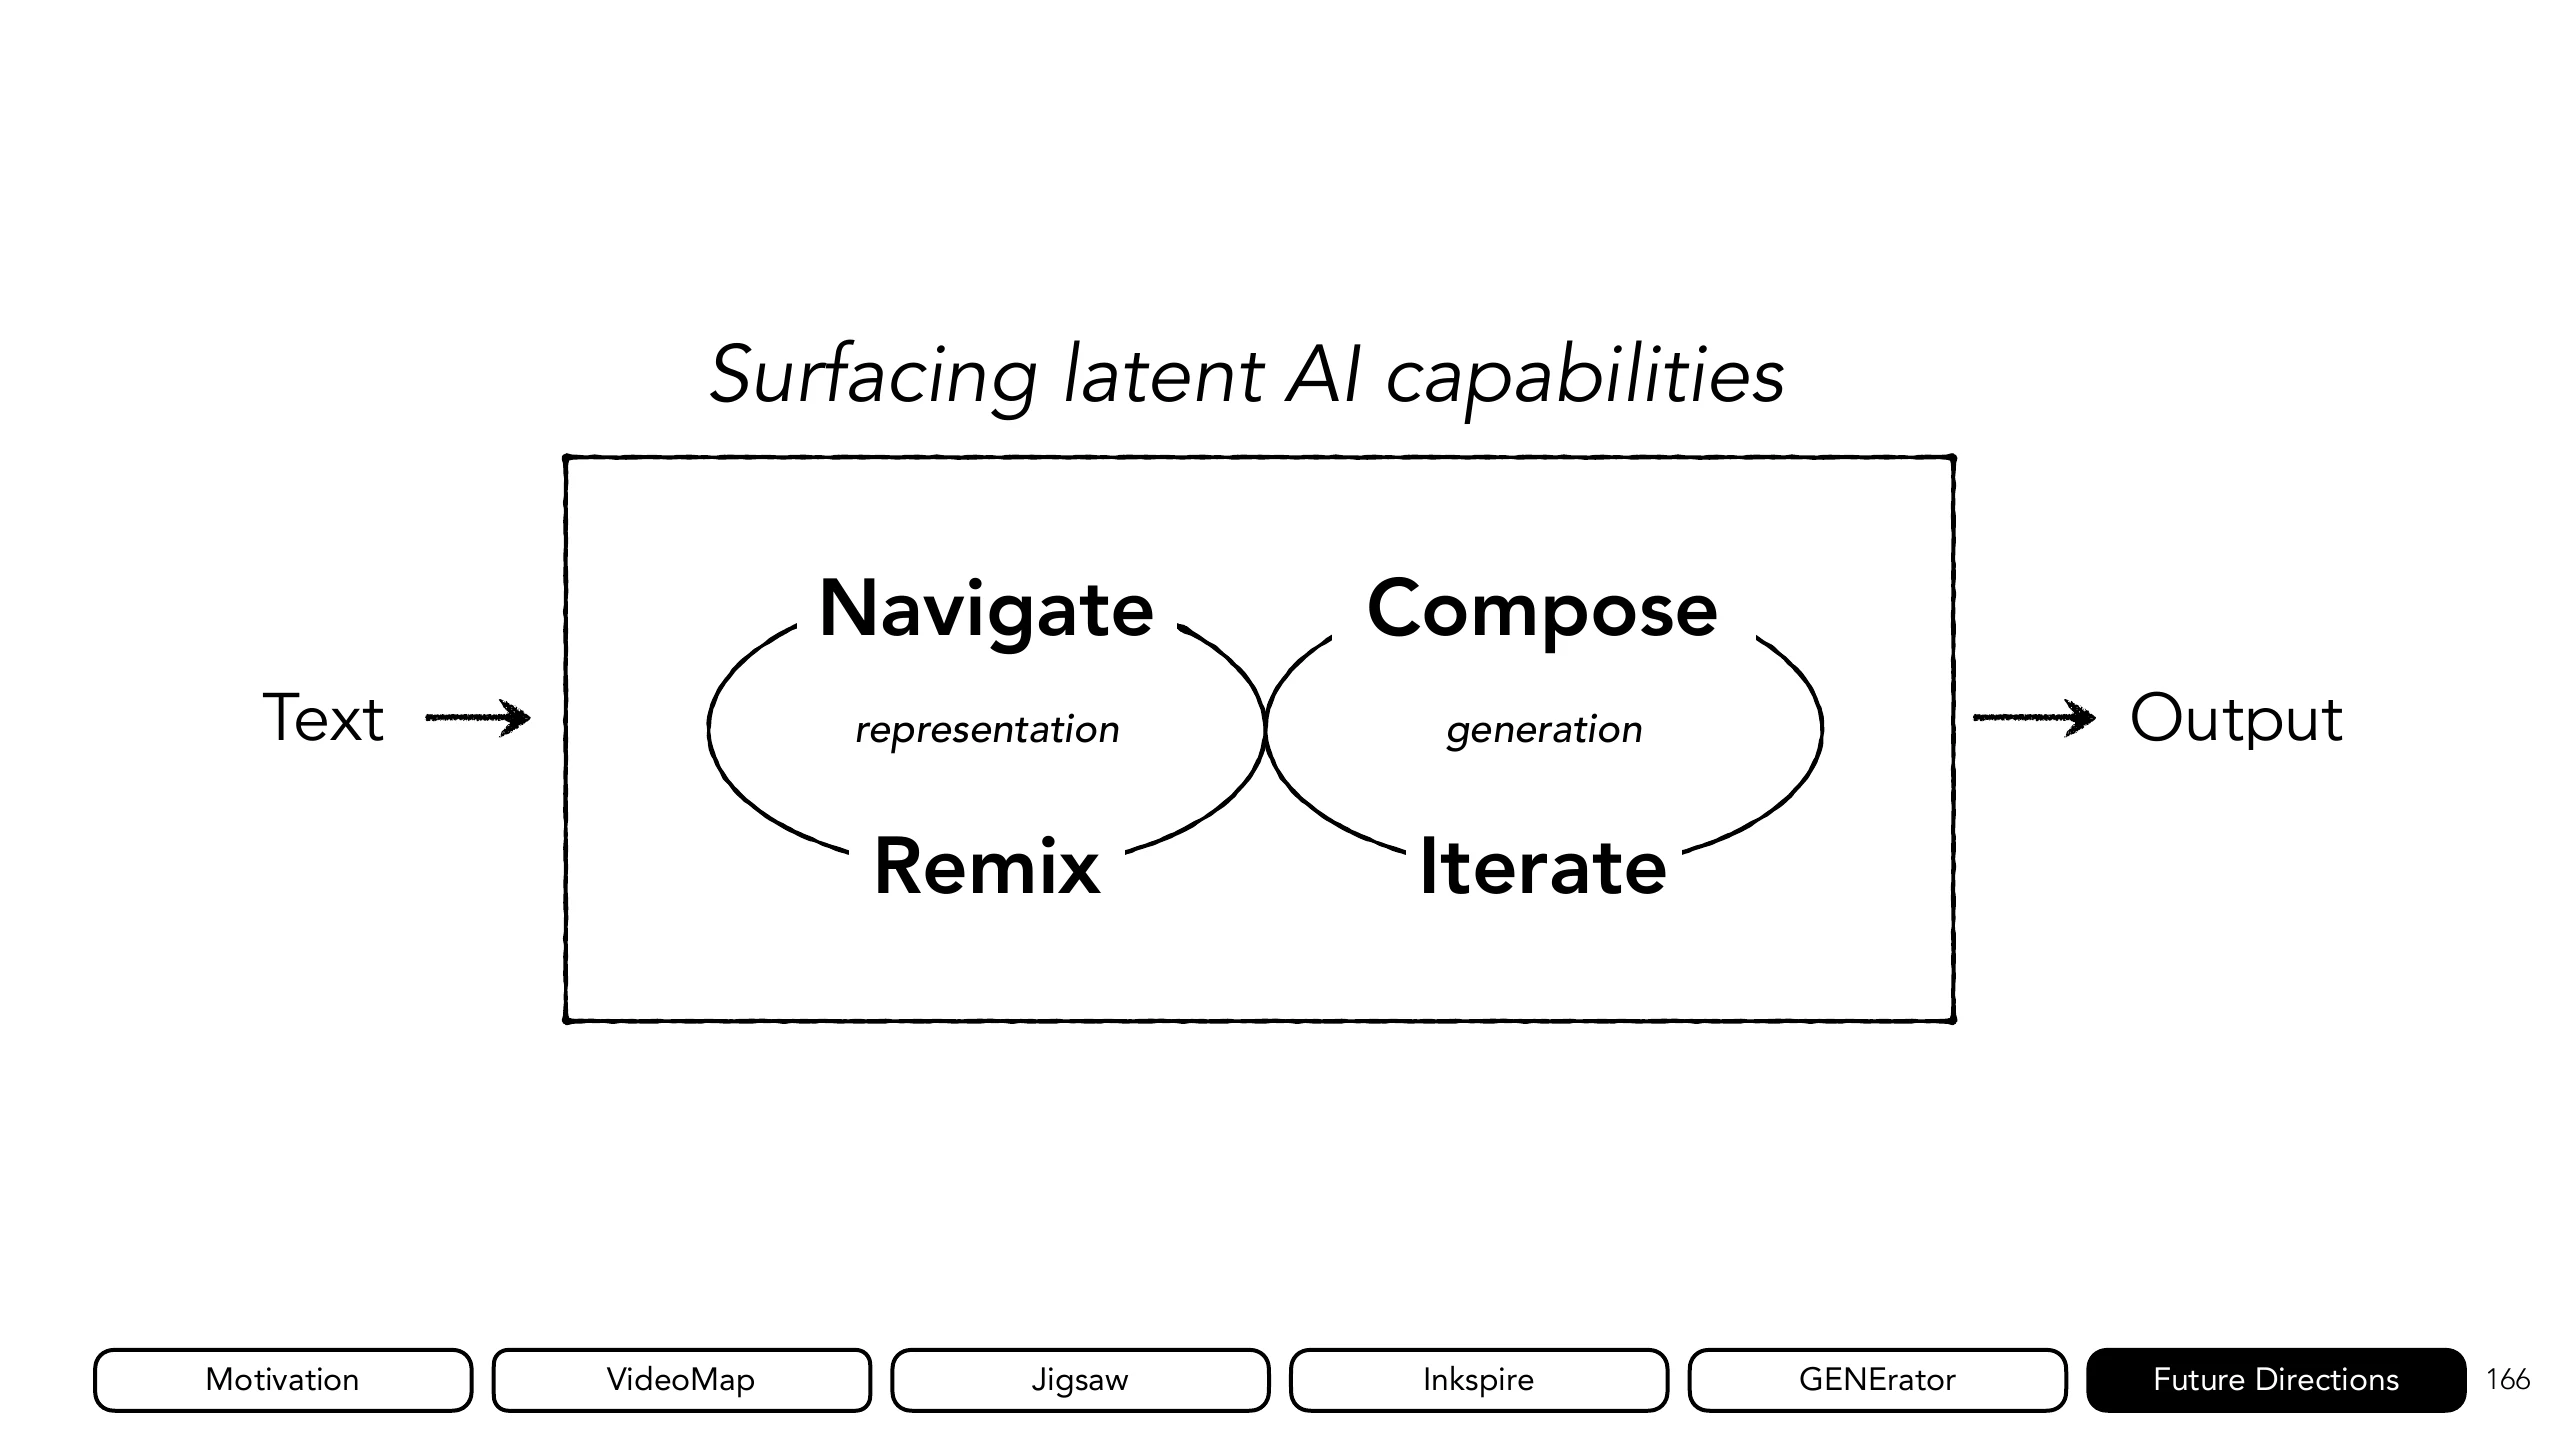
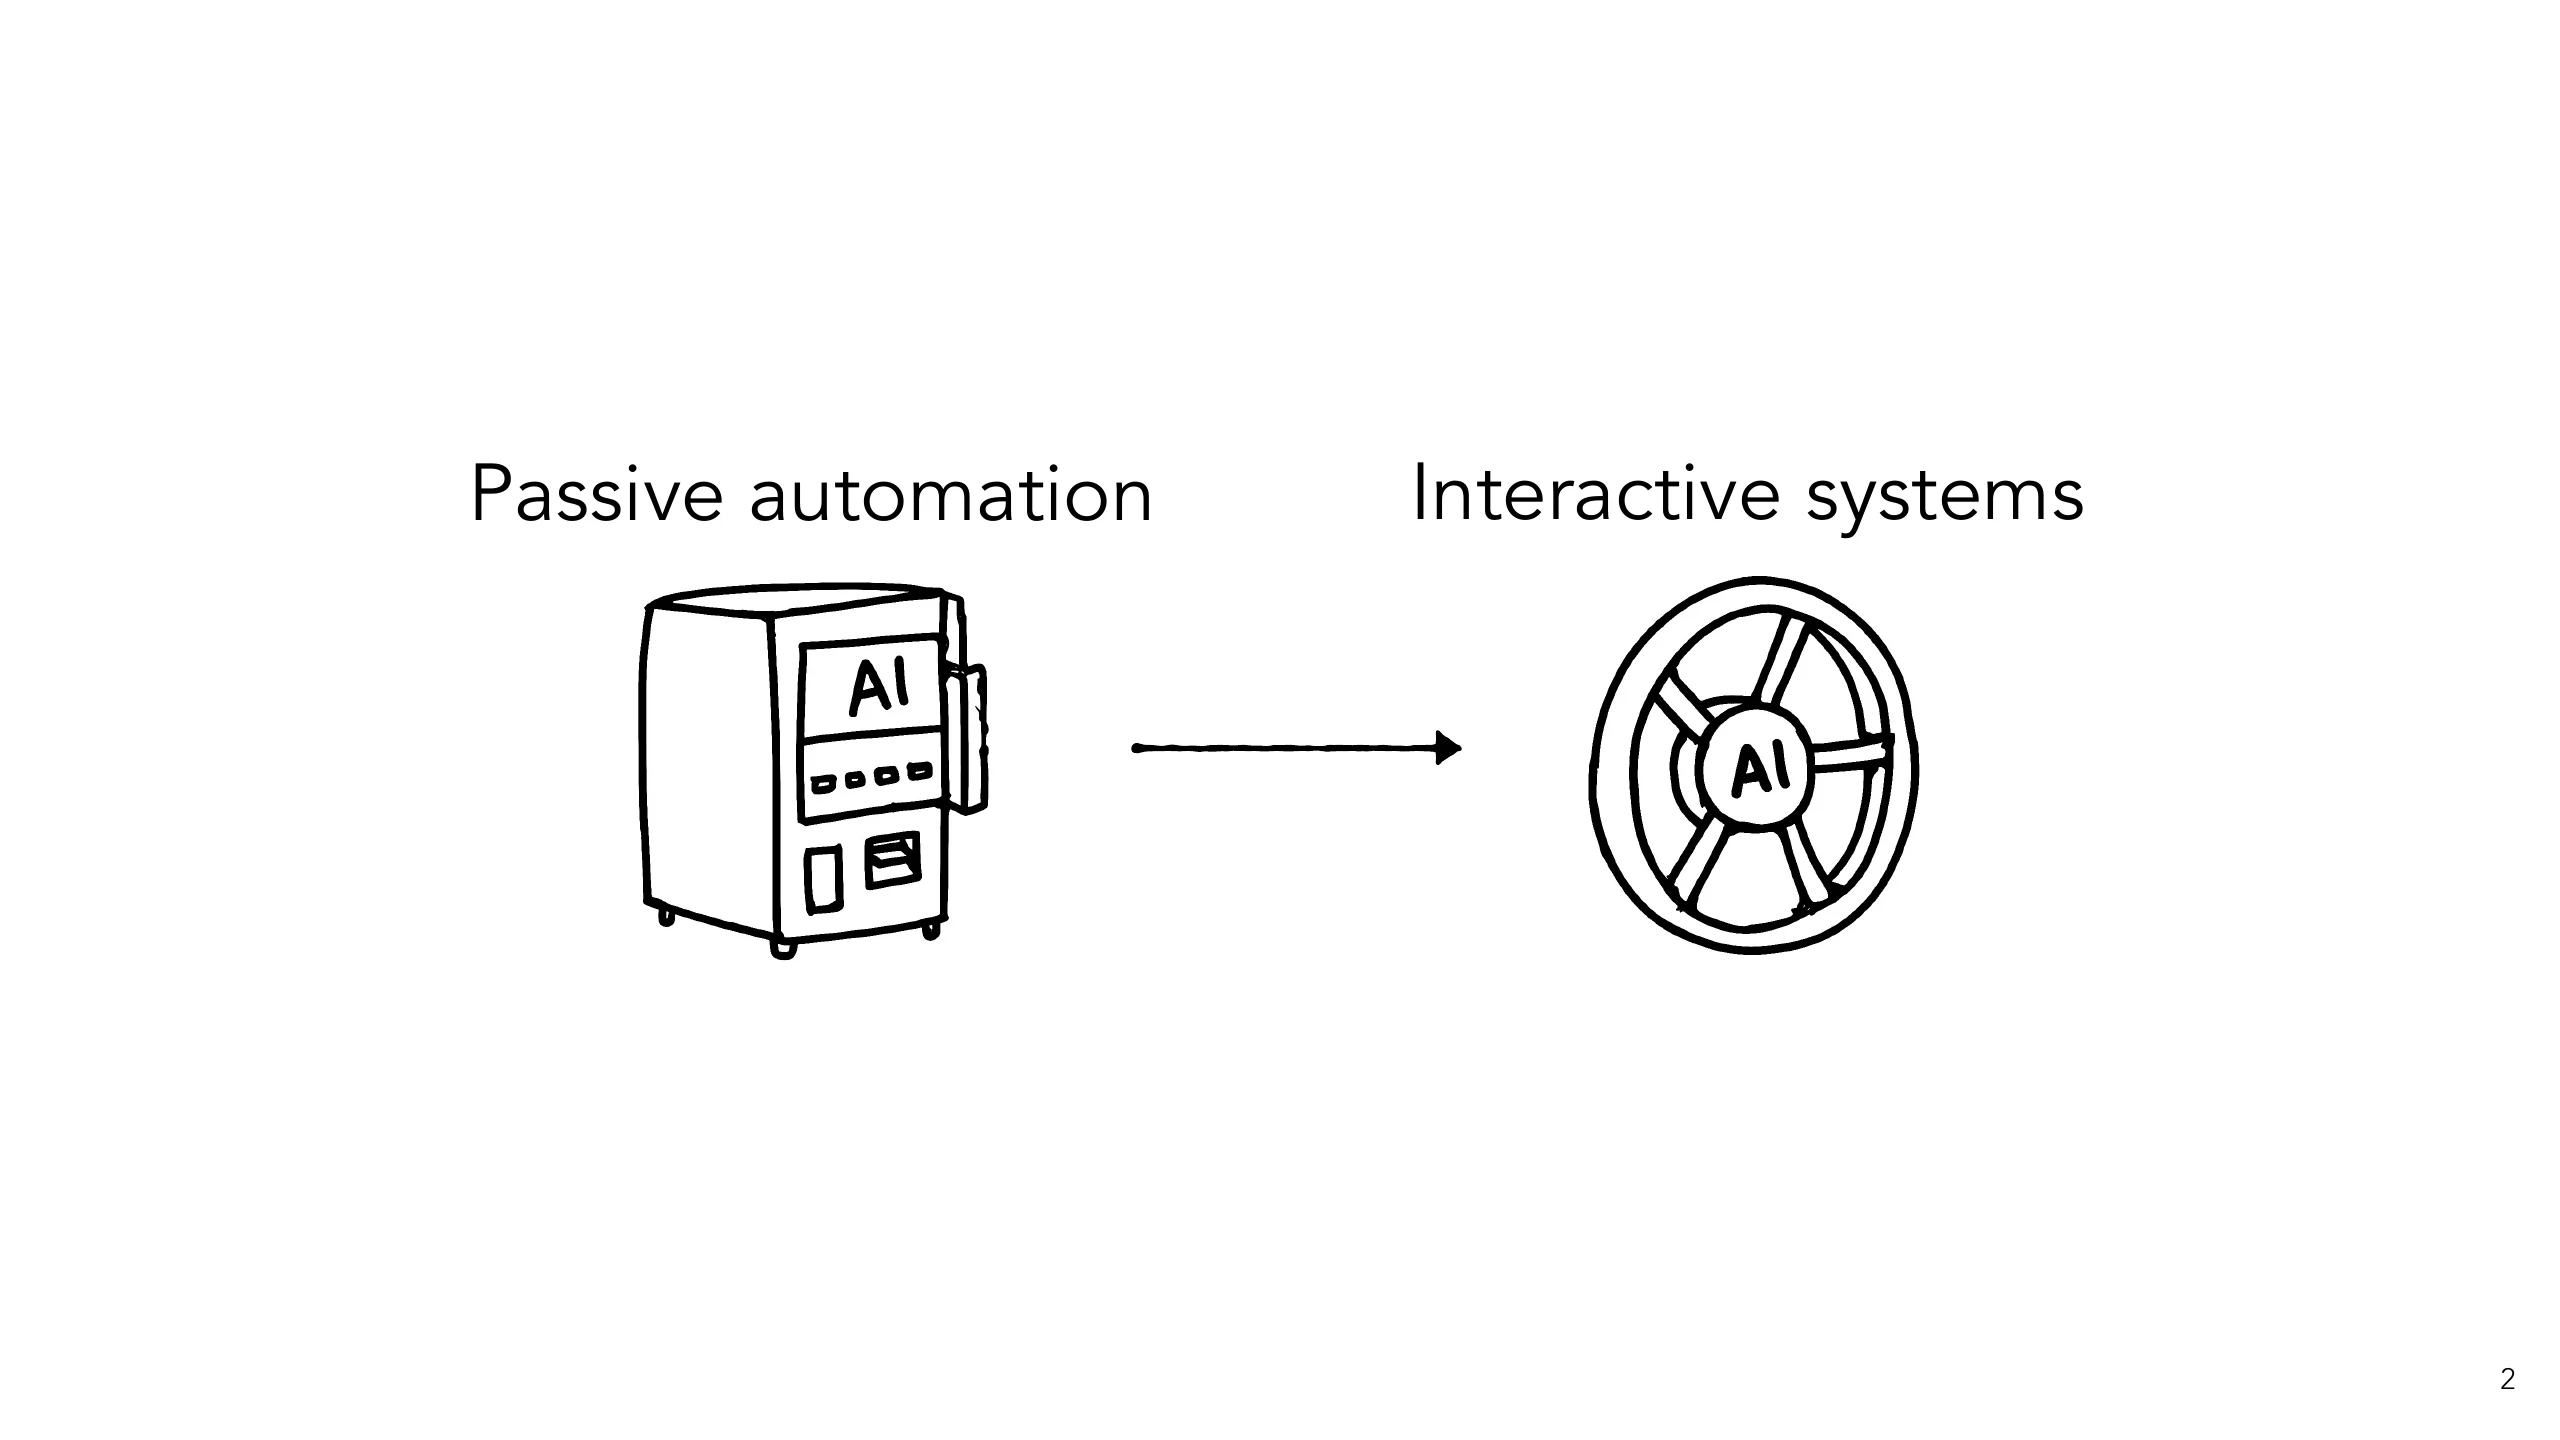
My research on human-centered AI focuses on designing interactive systems and models that make generative AI steerable. Today, people mostly steer AI with text prompts, describing what they want without seeing the range of what is possible. Instead, I build AI steering interfaces that turn a model's internal representations, such as its latent space and learned concepts, into controls people can see, explore, and directly manipulate. I study this through the lens of design, where goals are often ill-defined, take shape through exploration, and are hard to put into words.
Several questions I am exploring include:
- Latent Manipulation. What would direct manipulation look like for the latent spaces of AI models, and can the same operations generalize across different models and modalities?
- Steerable Models. How can we train models whose internal representations align with the abstractions people already use to think and create?
- Generative User Interfaces. When AI can generate interfaces in real time, how should they adapt to people's tasks, goals, and expertise?
- Steering Agents. When people delegate tasks to AI agents, how can they verify the agents' work, and when should agents surface decision points for human judgment?
Research
Highlights
Inkspire: Supporting Design Exploration with Generative AI through Analogical Sketching
CHI 2025 ACM Conference on Human Factors in Computing Systems
Inkspire lets product designers co-sketch with AI, turning each sketch into a high-fi design and back into a low-fi sketch scaffold, with analogies for abstract concepts.
VideoMap: Supporting Video Editing Exploration, Brainstorming, and Prototyping in the Latent Space
C&C 2024 ACM Creativity and Cognition
NeurIPS ML4CD 2022 NeurIPS Workshop on Machine Learning for Creativity and Design
VideoMap places video frames on a latent space map organized by shape, color, or meaning, so editors can create seamless transitions and edits.
Jigsaw: Supporting Designers to Prototype Multimodal Applications by Chaining AI Foundation Models
CHI 2024 ACM Conference on Human Factors in Computing Systems
Jigsaw lets designers build multimodal AI workflows by chaining foundation models like puzzle pieces.
GENErator: Supporting Design Style Exploration with Generative AI through Genetic Mixing
Preprint
GENErator treats AI image styles as genes in a latent style space, so designers can explore them with genetic operations (crossover, mutation, and natural selection).
AI Receipts: Supporting Blind and Low-Vision Users in Verifying Agent Actions with Just-in-Time Widgets
AI Receipts surfaces the small decisions and assumptions a web agent makes for screen reader users. Each verification is grounded in a task model dataset of 15K decision points mined from 1.7K videos (183 hours) of people doing everyday web tasks.
AI for Accessibility Toolkit
The AI for Accessibility Toolkit orchestrates AI agents to adapt any web page to a person’s abilities, and lets people author new personalized adapters from natural language.
Generative User Interfaces: A Definition and Design Space
Preprint
Generative User Interfaces defines GenUI and maps how systems vary across user, task, interaction, and technology.
Tracing Creativity: A Design Space For Creative Activity Traces in HCI
CHI 2026 ACM Conference on Human Factors in Computing Systems
Tracing Creativity reviews 133 creativity systems to map the traces of user activity they record (e.g., drafts, annotations) and the features those traces power.
Visual Lyrics: Generating Animated Text for Music Lyric Videos with an Augmented Text Editor
IUI 2026 ACM Conference on Intelligent User Interfaces
Visual Lyrics generates animated lyric videos in an augmented text editor, combining music analysis with LLM-written animations that semantically match the lyrics.
BioSpark: Beyond Analogical Inspiration to LLM-augmented Transfer
CHI 2025 ACM Conference on Human Factors in Computing Systems
BioSpark helps designers borrow ideas from a wide range of organisms, with LLMs mapping each organism’s mechanism onto the design problem and weighing trade-offs.
NoTeeline: Supporting Real-Time, Personalized Notetaking with LLM-Enhanced Micronotes
IUI 2025 ACM Conference on Intelligent User Interfaces
NoTeeline lets people jot quick micronotes while watching videos, then an LLM expands them into full notes in their own writing style.
Gen4Gen: Generative Data Pipeline for Generative Multi-Concept Composition
BMVC 2025 British Machine Vision Conference
Gen4Gen creates a dataset for personalizing text-to-image models with several concepts at once, composing them into realistic scenes with chained foundation models.
Videogenic: Identifying Highlight Moments in Videos with Professional Photographs as a Prior
C&C 2024 ACM Creativity and Cognition
NeurIPS ML4CD 2022 NeurIPS Workshop on Machine Learning for Creativity and Design
Videogenic finds highlight moments in videos with professional photographs as a prior, inspired by how photographers tend to capture an activity’s most remarkable moments.
Soundify: Matching Sound Effects to Video
UIST 2023 ACM Symposium on User Interface Software and Technology
NeurIPS ML4CD 2021 NeurIPS Workshop on Machine Learning for Creativity and Design
Soundify matches, syncs, and mixes sound effects for video, exploiting CLIP’s activation maps as a zero-shot object detector.
Learning Personal Style from Few Examples
DIS 2021 ACM Conference on Designing Interactive Systems
PseudoClient uses metric learning to model a client’s graphic design style from a handful of liked and disliked examples.
ARchitect: Building Interactive Virtual Experiences from Physical Affordances by Bringing Human-in-the-Loop
CHI 2020 ACM Conference on Human Factors in Computing Systems
ARchitect lets an assistant use augmented reality to map physical objects to virtual ones with matching affordances, so a VR player can interact with their real surroundings.
SeqDynamics: Visual Analytics for Evaluating Online Problem-solving Dynamics
EuroVis 2020 Eurographics Conference on Visualization
SeqDynamics is a visual analytics tool that helps instructors evaluate students’ cognitive skills and non-cognitive traits from how they solve problems over time.
Learning to Film from Professional Human Motion Videos
CVPR 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition
Learning to Film uses imitation learning to teach a drone to film autonomously, copying how professionals move the camera in cinematic drone videos.
Courses
 Human-AI Interaction
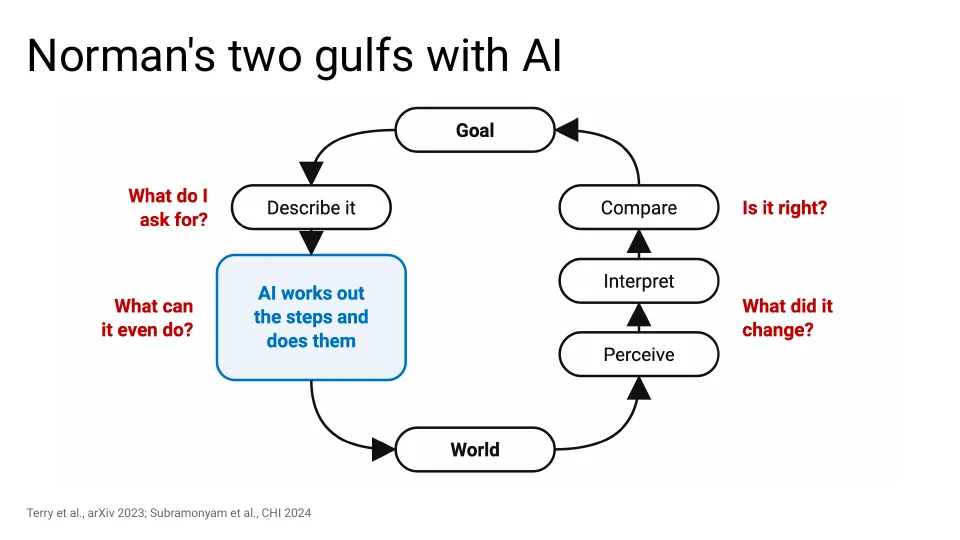
How is designing with AI different from designing conventional software?
 Machine Learning for Design
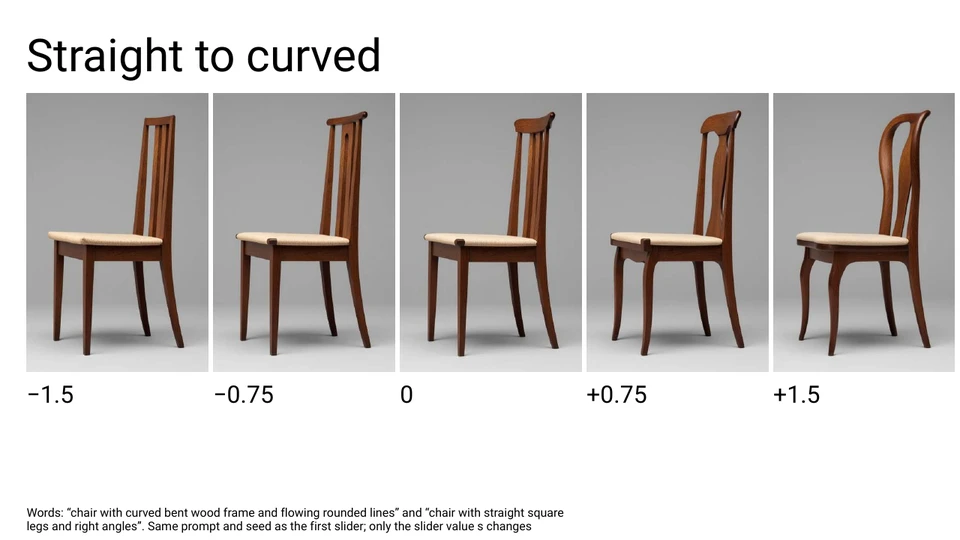
What makes machine learning uniquely difficult to design with as a material?
Recent Highlights
- Excited to serve on the CHI 2027 and C&C 2027 Program Committees as an Associate Chair, and on the SIGGRAPH 2027 Technical Papers Committee.
- Alice, Robert, and I hosted a SIGGRAPH 2026 Birds of a Feather.
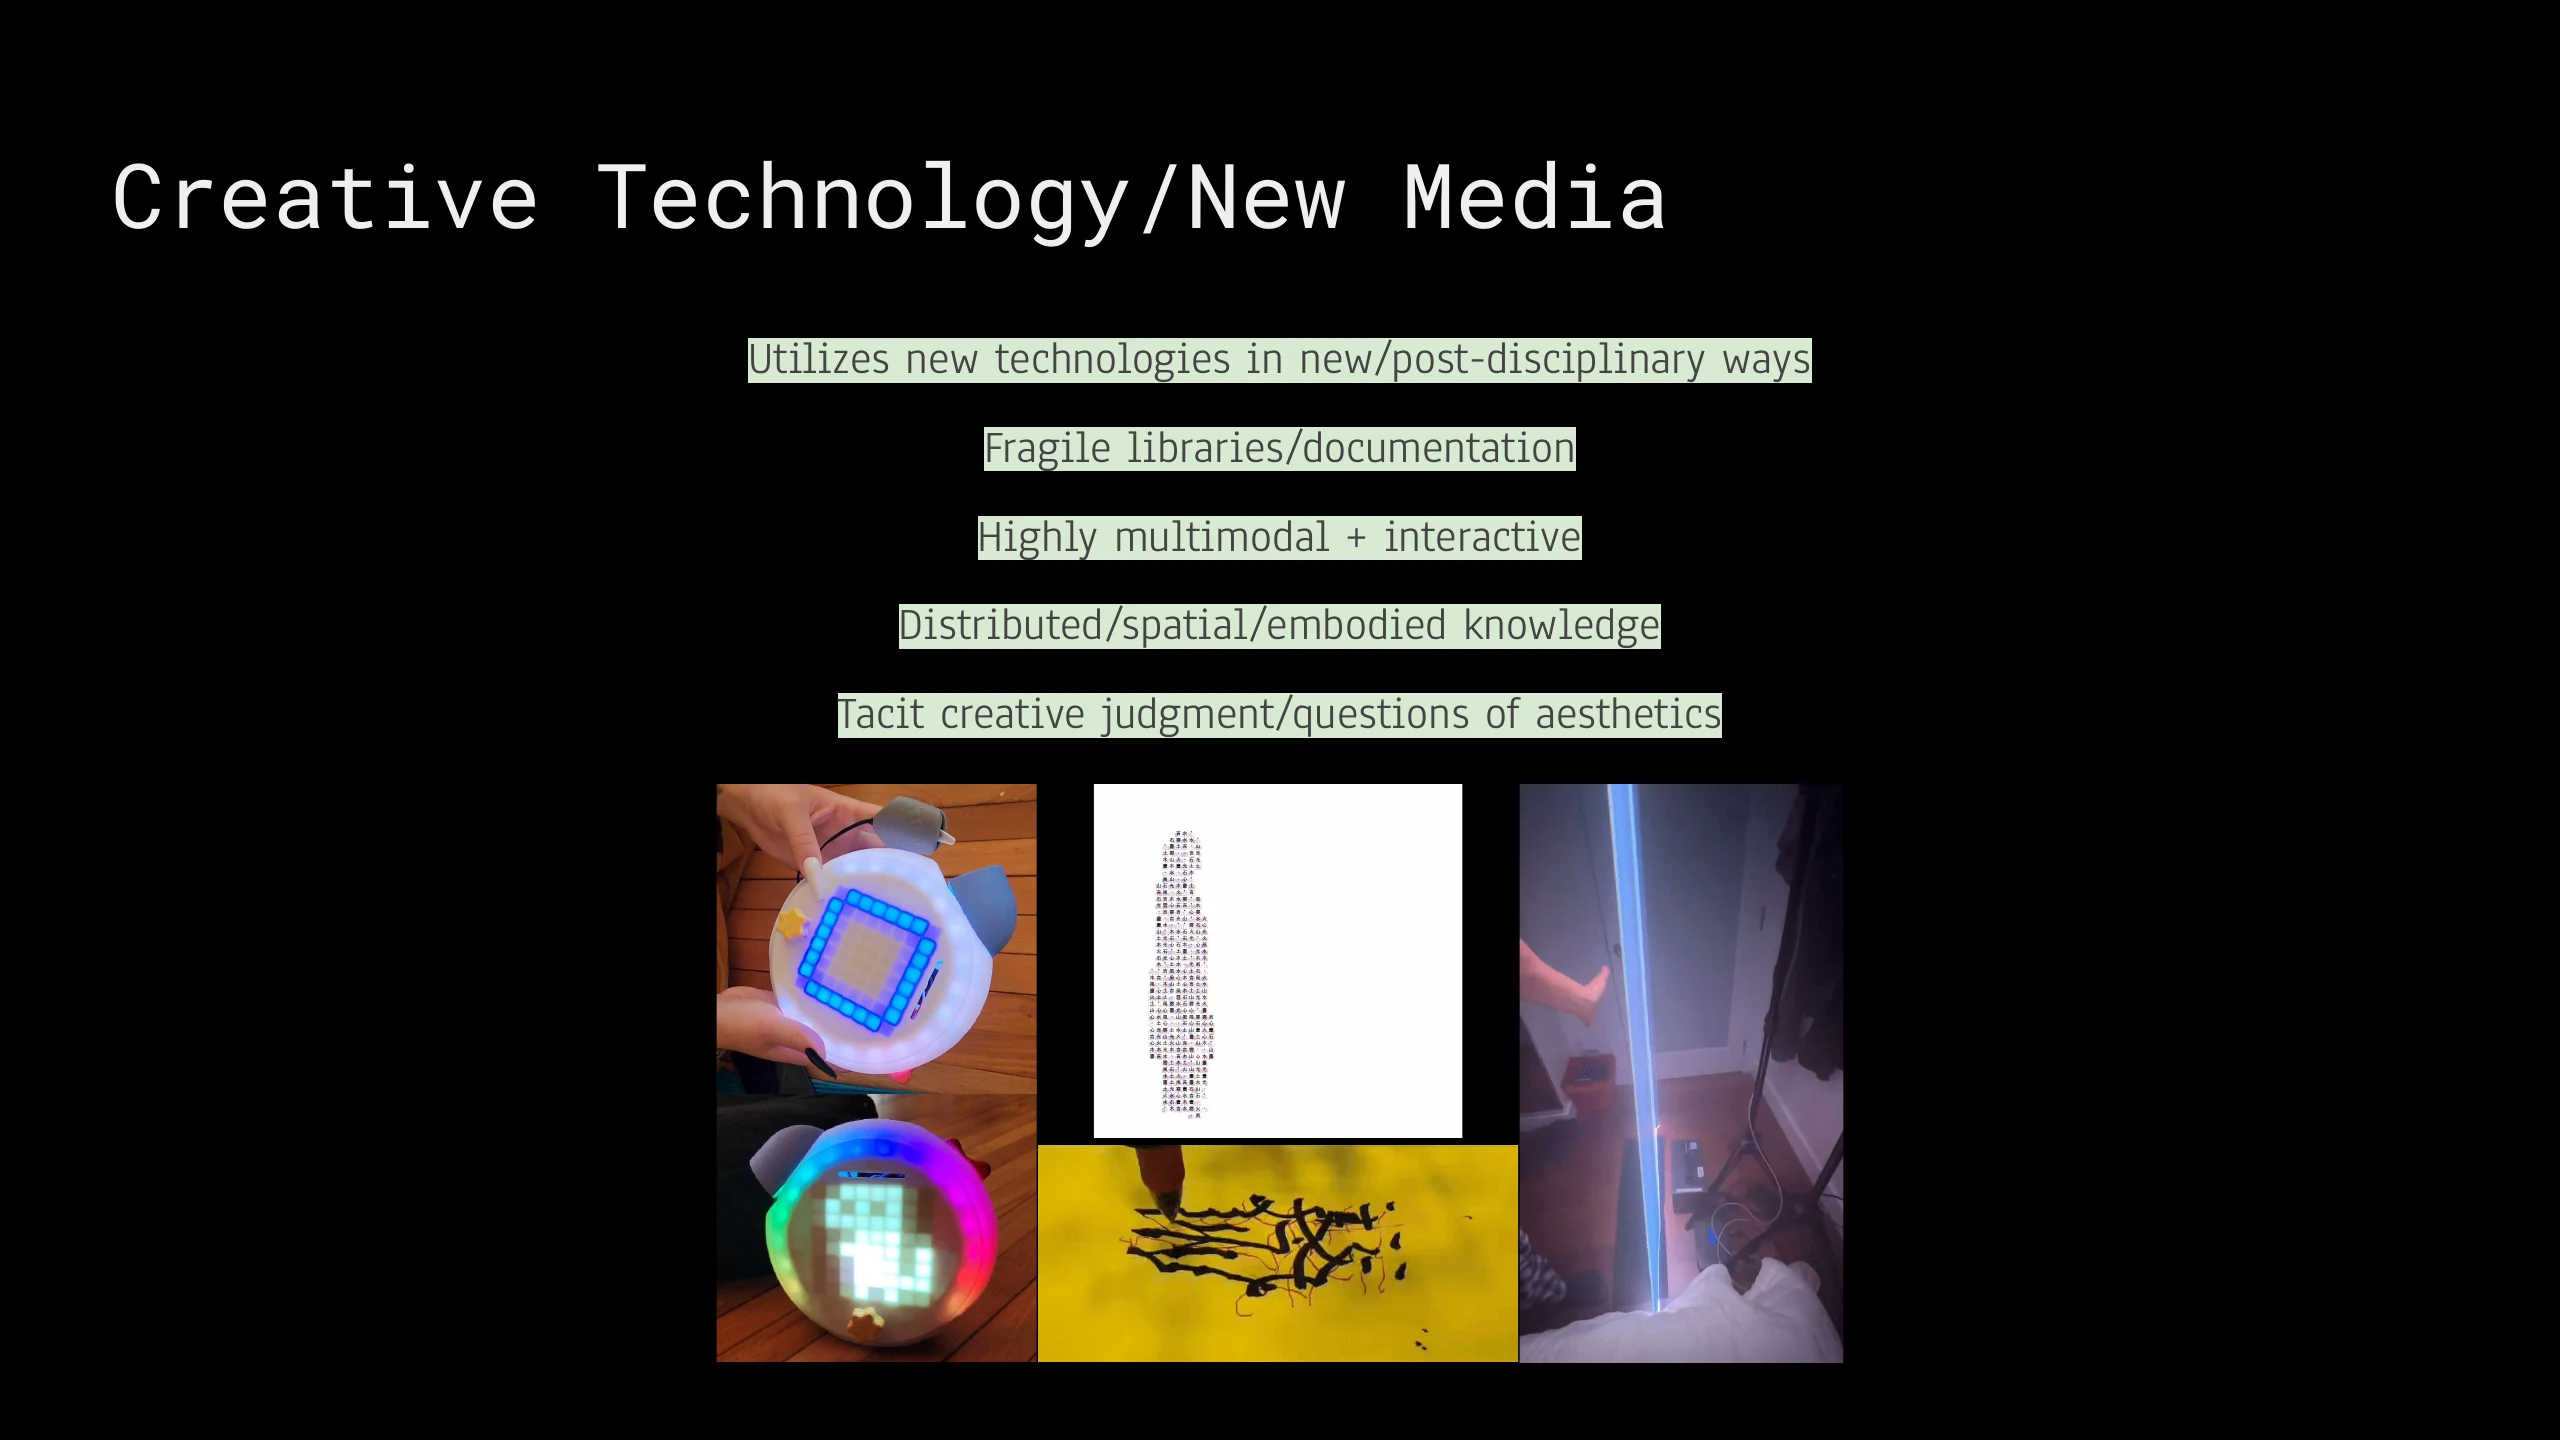
- Gave a talk at the Adobe Research HCI Seminar.
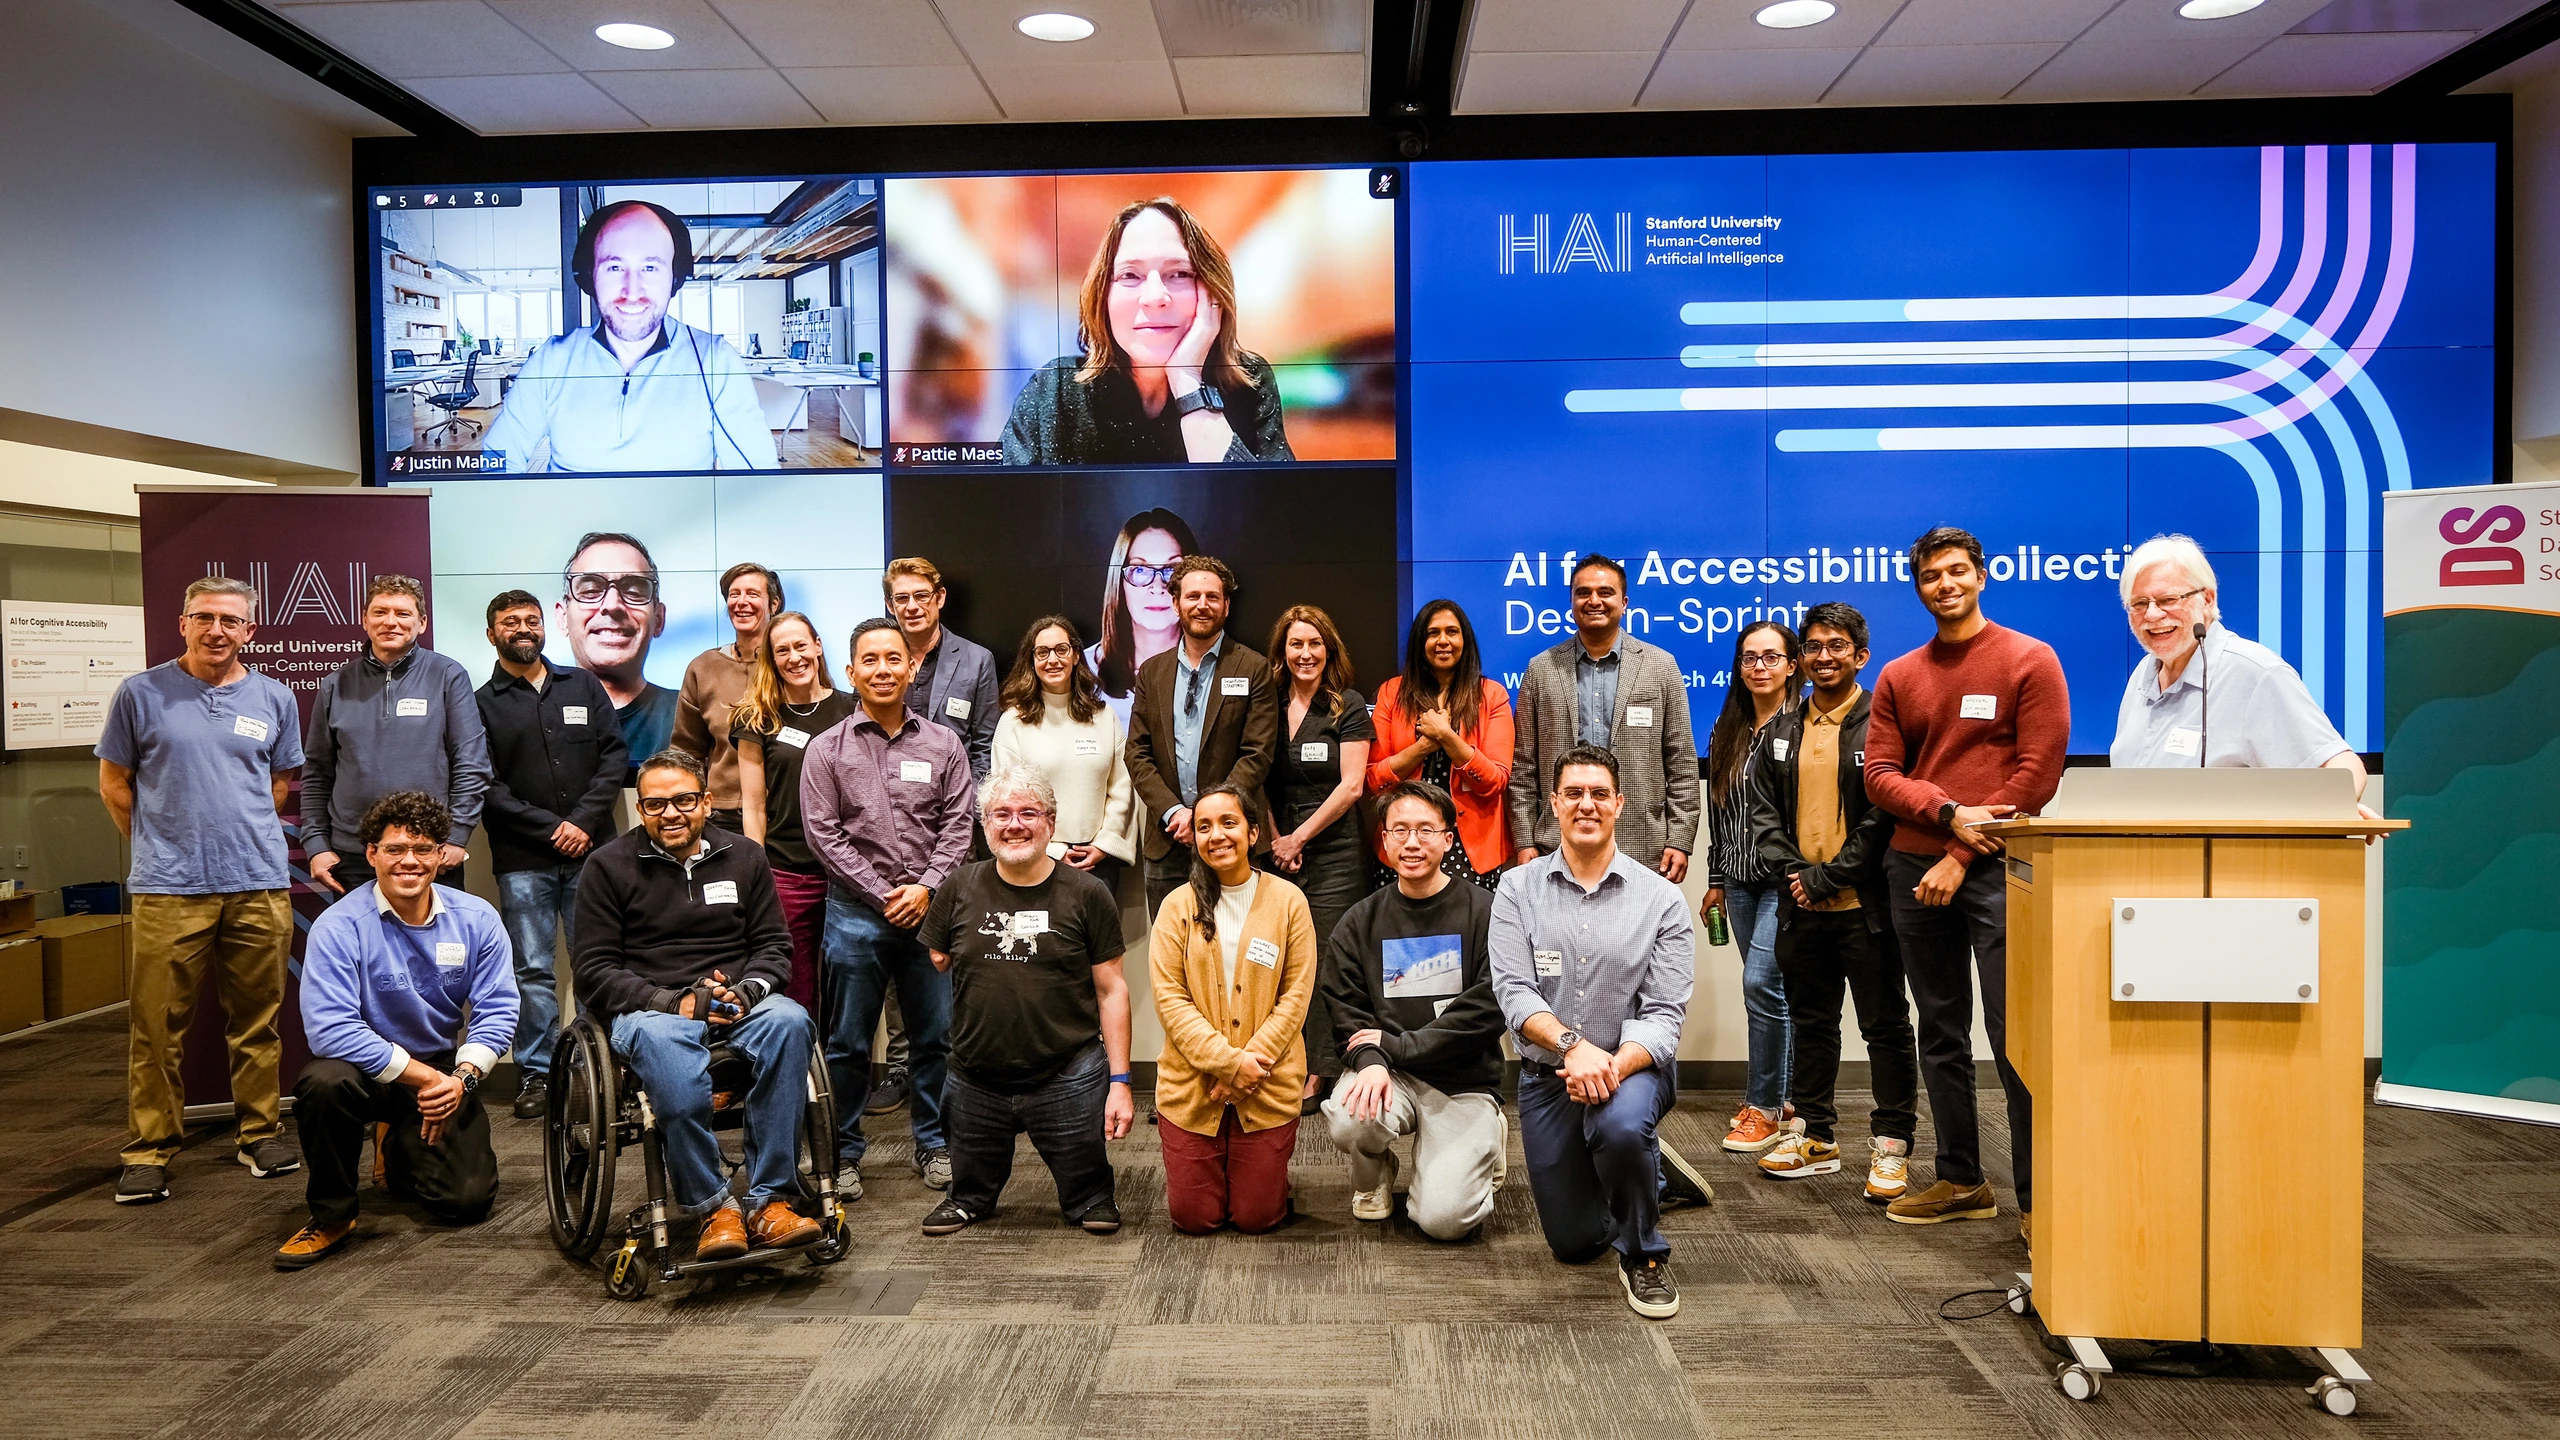
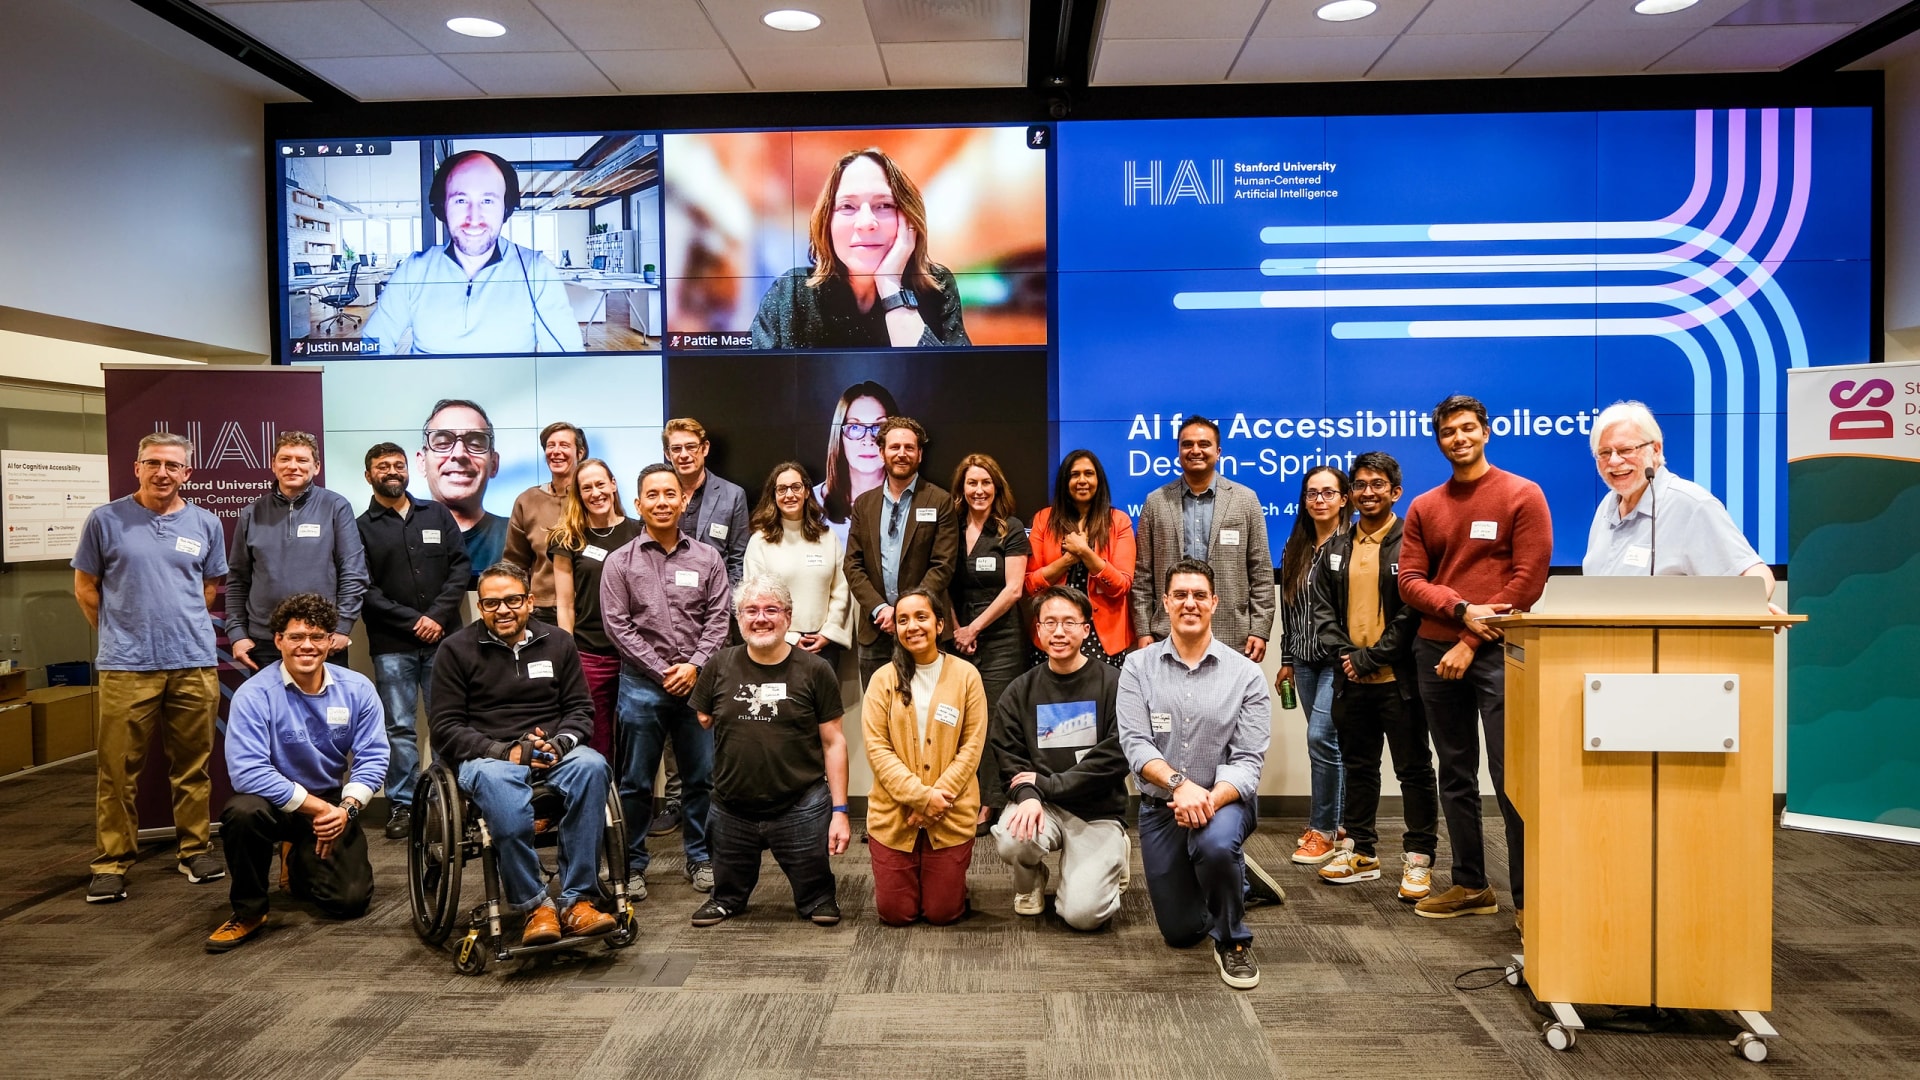
- We held a three-day design sprint at Stanford HAI on rethinking accessible computing with AI agents, as part of the AI for Accessibility Collective.
- Served as a judge for the DIS 2026 Student Design Competition in Singapore.
- Defended my PhD thesis on AI steering interfaces. Thank you to my advisor Nik and committee members Niki Kittur, David Lindlbauer, and Michael Terry (Google DeepMind).
- Gave the keynote at the CHI 2026 Human-AI-UI Workshop in Barcelona.
- Served on the CHI 2026 (Posters) and C&C 2026 Program Committees as an Associate Chair.
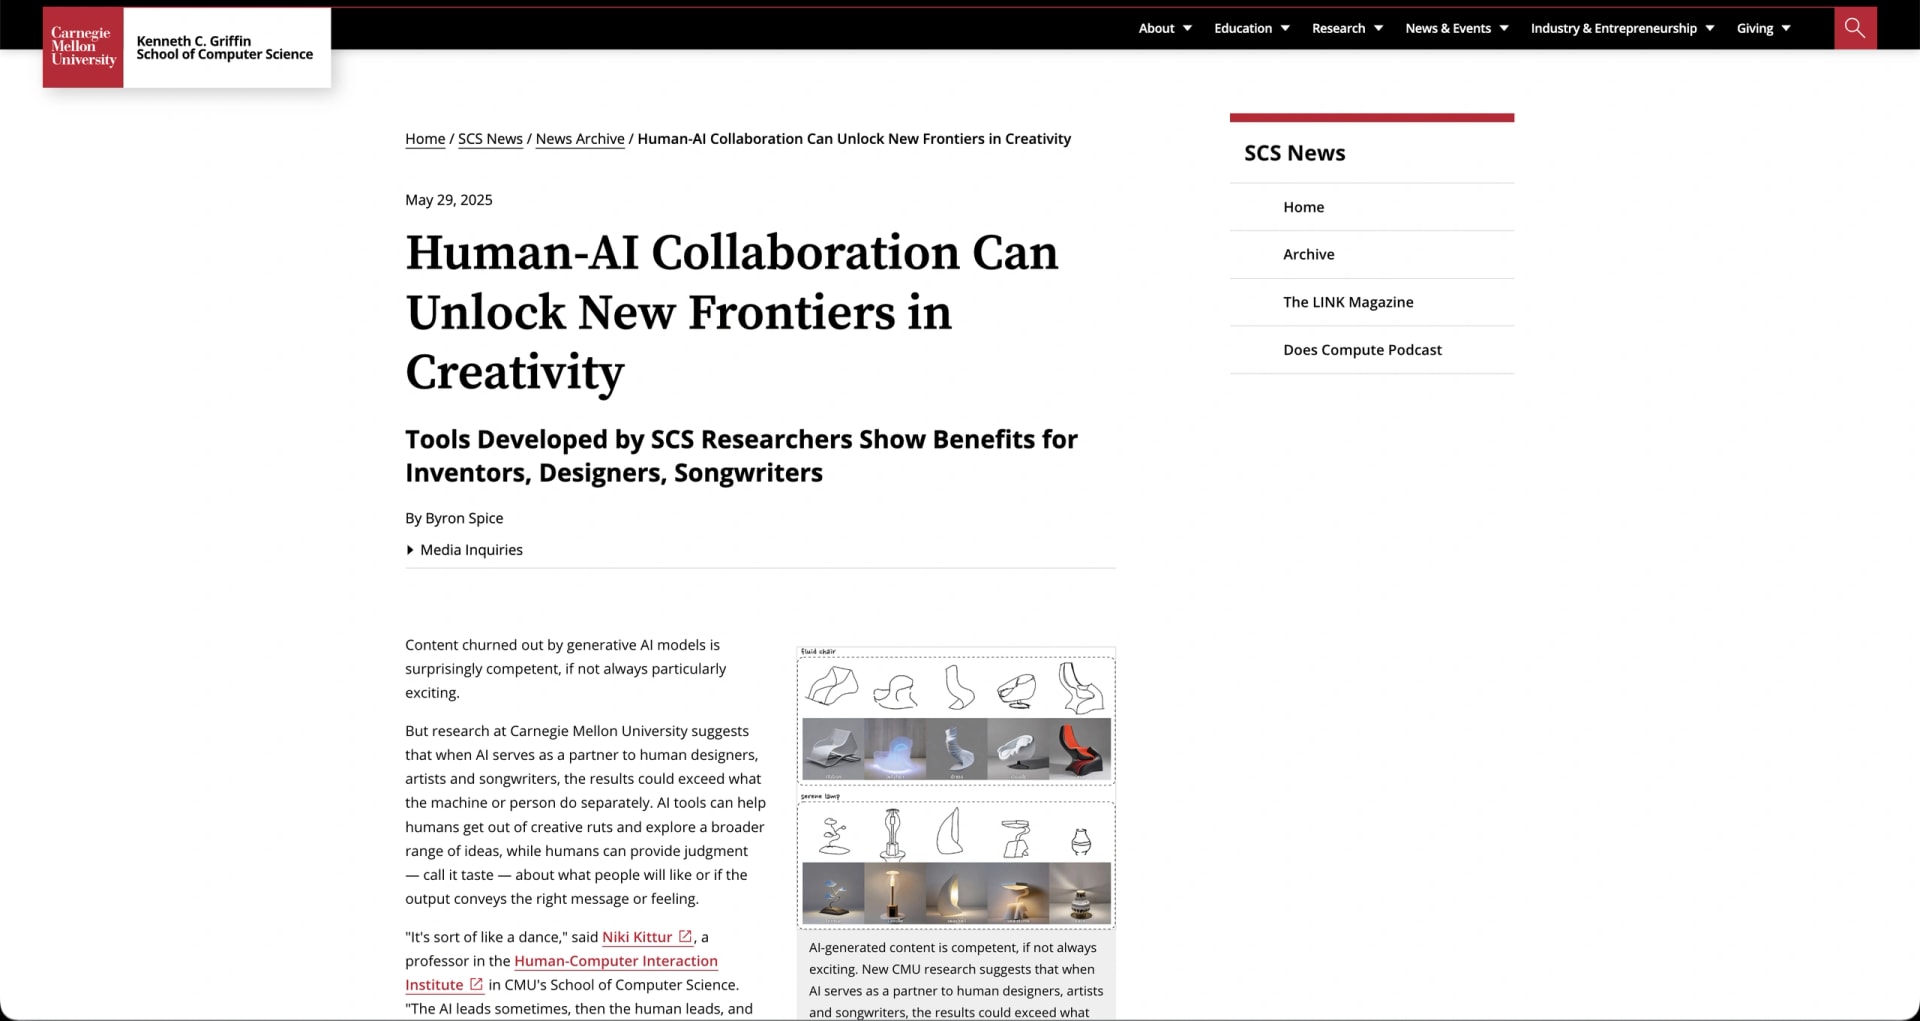
- Our Inkspire and BioSpark work with the Toyota Research Institute was featured by CMU.
- Our BioSpark paper received a Best Paper Honorable Mention at CHI 2025.